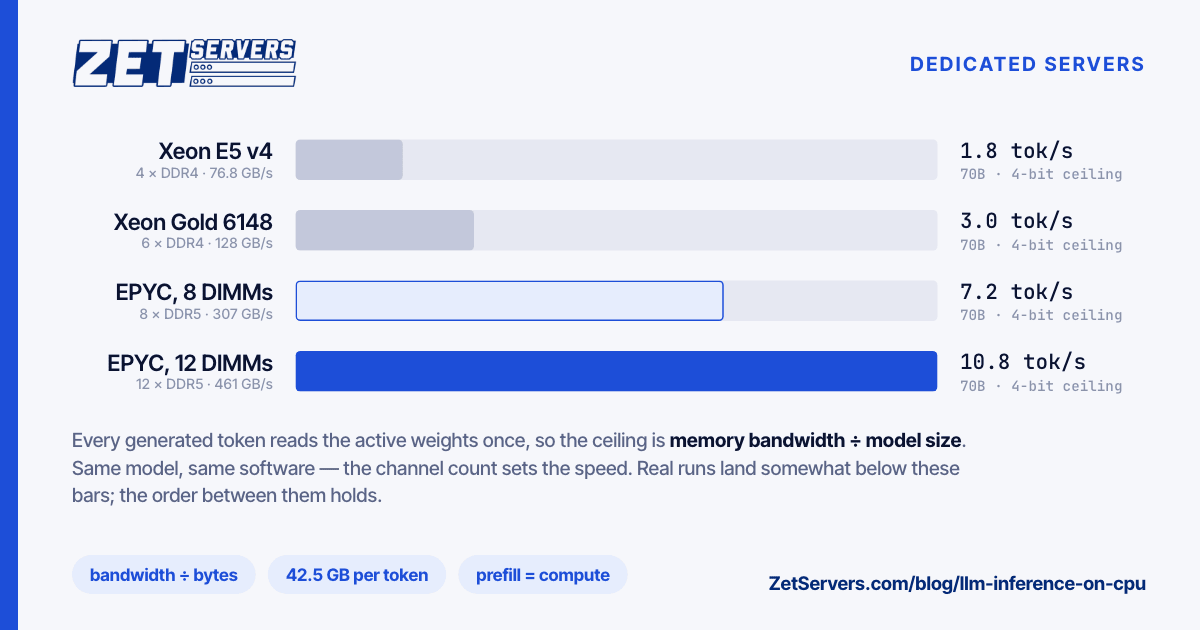
LLM inference on CPU: sizing a server by memory bandwidth
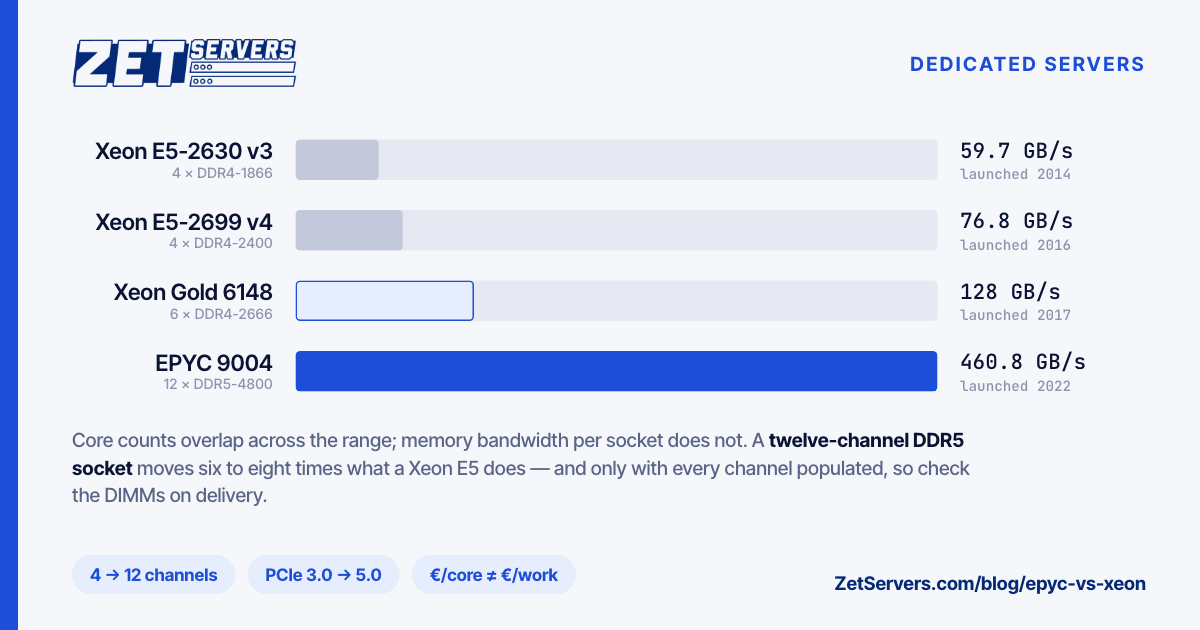
Generating a token means reading the model's active weights once, so a CPU server's speed ceiling is its memory bandwidth divided by the model's size. The arithmetic, the catch in prompt processing, why two sockets are not twice as fast, and the workloads a big-memory EPYC box genuinely suits.